After42: Can AI Propose Interesting Research Questions?
TL;DR.In The Hitchhiker’s Guide to the Galaxy, a supercomputer finds that the ultimate answer to life, the universe, and everything is 42. However, the question itself remains unknown. In After42, we move beyond answering questions to ask whether AI can propose interesting research questions. We built Agent42, a multi-agent workflow that develops research questions by attempting to solve them. Domain experts across mathematics and the sciences find some of its questions genuinely interesting.
Draft preview · Overleaf d3d38e61 Introduction
Frontier AI systems have made striking progress on difficult, well-defined open problems across the sciences. In mathematics, OpenAI has announced a resolution of the Navier–Stokes existence and smoothness problem (OpenAI, 2026), and in theoretical physics, AI systems have derived exact analytical solutions for the power spectrum of gravitational radiation emitted by cosmic strings (Brenner et al., 2026). However, research is broader than solving given problems (De Toffoli and Duede, 2026; Tao, 2026). Researchers also develop new concepts, theories, and tools, and choose which directions to explore. These activities are intertwined and continually change what researchers can investigate and understand (Thurston, 1994; Avila et al., 2026). We therefore ask how AI can take part in this broader enterprise.
Posing research questions is one important part of that enterprise. It determines where researchers invest their effort. Much of the value of research is created before a problem is solved (Corwin, 2026). As AI solves more of the problems that people have posed, sustained progress requires posing new ones. Across the fields we study, novel and difficult questions are relatively easy to generate, but genuinely interesting ones are rare and hard to judge. As a concrete step toward AI that participates more broadly in research, we study whether AI can propose questions that domain experts find genuinely interesting and whether it can judge which questions are interesting.
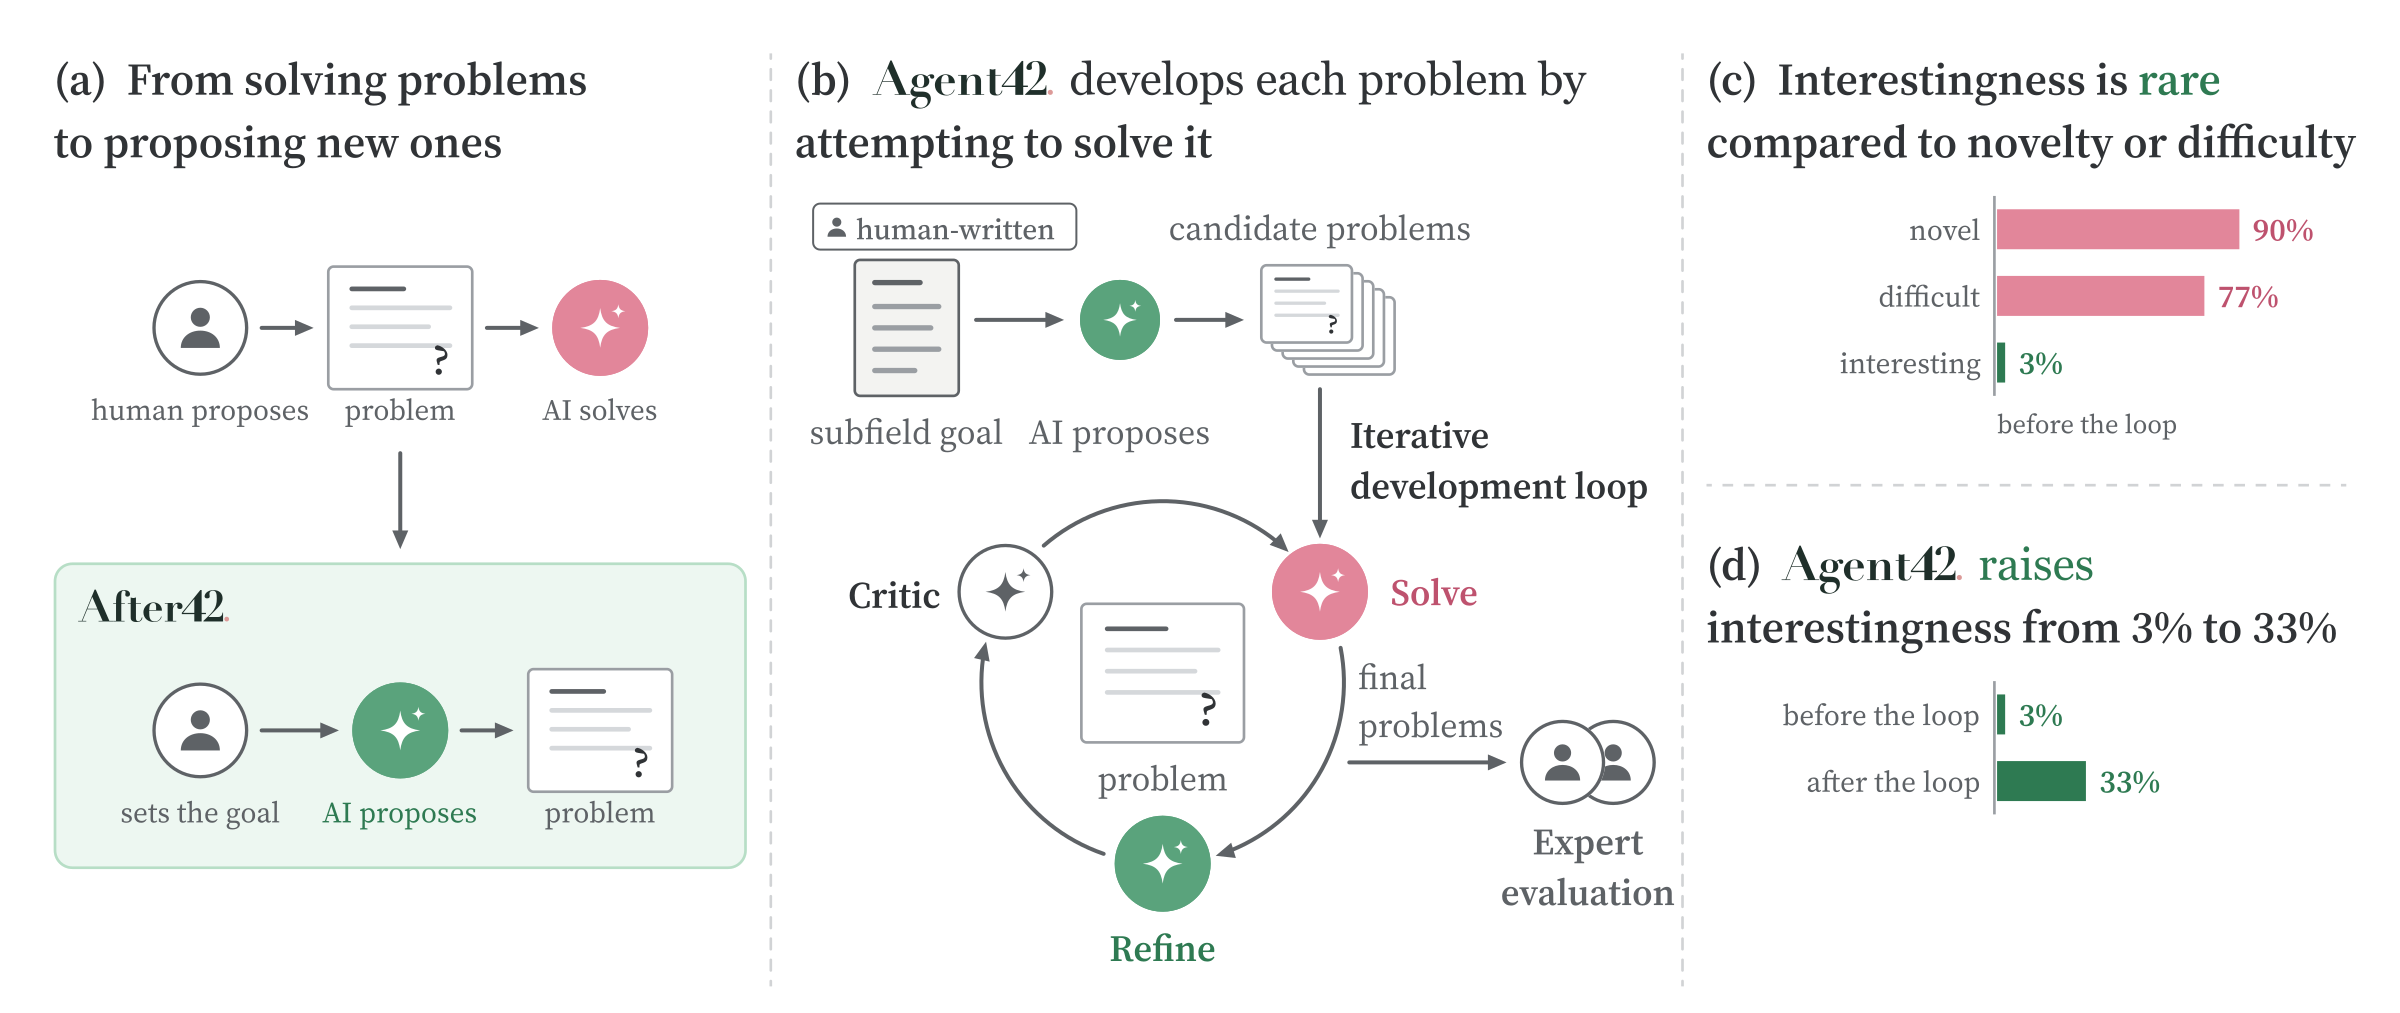
To answer the first question, we build Agent42, a multi-agent workflow whose central idea is to develop questions by attempting to solve them. The insight needed to formulate an interesting question often emerges only through investigation. In mathematics, for example, conjectures and concepts are repeatedly revised in the course of attempted proofs (Lakatos, 1976). Because interesting questions are rare, Agent42 generates a broad pool of literature-grounded candidate questions and filters out unsuitable ones. It then develops the surviving questions through rounds of exploratory solving and revision. Solution attempts can reveal where the central difficulty lies or uncover structure that suggests a different research target.
Across mathematics, statistics, theoretical computer science, and physics, experts judge 45 of 137 final questions generated by GPT 6 Astra genuinely interesting and worth pursuing. Results are uneven across fields, with 33 of 70 questions judged interesting in mathematics compared with 5 of 35 in statistics. In a separate expert study in mathematics using GPT 5.6 Sol, Agent42 raises the proportion of questions judged interesting from 3% among initial proposals to 33% among final questions (Figure 1(d)). Development trajectories show how solution attempts sharpen or redirect questions.
Model judges cannot yet fully replace expert research taste. Their preferences are reproducible and steerable, but their rankings do not consistently prioritize questions that experts find genuinely interesting. Conditioning judges on researcher profiles may improve alignment with those experts’ preferences, but does not resolve this gap. Reliable automatic evaluation therefore remains a challenge for scaling question generation.
Beyond proposing questions, we envision AI and researchers jointly shaping research directions and developing new concepts, theories, and tools. Solving questions alone cannot build a comprehensive understanding. Posing good questions requires understanding what is known, how ideas connect, and which gaps are worth pursuing. Our long-term goal is to build a more comprehensive understanding of mathematics and the sciences.
2 How Agent42 Works
Agent42 starts from a subfield goal written by researchers, such as the example below. Grounded in a research pack of the literature, it proposes a broad pool of candidate questions, and a critic filters out weaker ones. It then develops the most promising questions through rounds of solution attempts and revision, with the critic evaluating each proposed change (Figure 1(b)).
The goal of the theory of phase transitions in random structures is to understand how a large number of local random rules produce qualitative change at the macroscopic scale, and to explain what these qualitative changes correspond to in real systems. The questions of interest are why a system switches abruptly from one type of behavior to another as a parameter varies, where the critical threshold lies, what new geometric, dynamical, informational, or algorithmic structure appears near it, and which phenomena are universal rather than tied to model details. The aim is to discover new phenomena, mechanisms, critical behavior, and universal laws, and to explain why they matter for real systems.
Step 0. Build the research pack. We first build a research pack containing a literature summary, an index of relevant papers and their main results, and open questions collected from the literature. The pack serves as a shared reference for agents throughout the workflow.
Step 1. Propose candidate questions. Interesting questions are rare and difficult to produce in a single pass, so Agent42 generates a larger pool than the final collection needs.
Proposer agents receive the subfield goal, instructions, and the pack’s literature summary as context. They can consult the pack as needed to propose seed questions, with different hints encouraging diverse proposals. Each seed question undergoes literature checks and short solution attempts to remove duplicate candidates, previously proposed questions, and questions that remain ill posed after attempted repair.
Step 2. Iterative development loop. In each round, solver agents receive an additional budget to try to solve the candidate questions, building on records from earlier attempts or exploring new approaches. These attempts may yield partial results, reveal obstacles, or uncover new structure. For each remaining candidate question, a development agent uses these findings and the literature record to guide further development. It uses multiple subagents to independently explore possible directions, then selects the most promising direction to develop the question further.
Model judges compare the current and revised questions without knowing which is the revision. A revision is accepted only if all judges prefer it. A fresh agent checks the selected question for prior answers, formulation defects, and unsupported claims. It makes minimal repairs that preserve the target or removes questions that remain ill posed. Model judges rank the survivors before the next round.
Expert evaluation. Domain experts assess whether the questions are interesting and worth pursuing. Our evaluation covers subfields in mathematics, statistics, theoretical computer science, and physics. All reviewers are PhD researchers or professors in the relevant subfield. Each question we label expert-verified has been assessed for research interest by at least one professor. Experts receive the complete question, subfield goal, and related work. They evaluate the final questions unless an ablation or case study specifies another version.
3 Main Results: Interesting Questions and Where They Come From
3.1 Experts find some questions genuinely interesting
Experts judged 45 of 137 final questions genuinely interesting and worth pursuing. Figure 2 summarizes the evaluations by subfield.
Positive expert comments emphasized natural, well-motivated questions whose answers could deepen understanding. Recurring themes included uncovering new structure, explaining mechanisms, and testing or refining existing ideas. The examples below summarize three reviewed probability questions and quote individual expert assessments.
Scatter $n$ random points on a sphere in $d$ dimensions and connect two points when they are close, with the threshold set so that each pair is connected with probability about $1/n$. At this density the graph sits at the threshold where large connected clusters first appear. Compare it with a graph that connects each pair independently with the same probability. Geometry makes triangles more likely, since two neighbors of a point tend to be close to each other. When $d$ is of order $(\log n)^3$, is the geometric graph indistinguishable in the limit from the independent graph with a random, Poisson-distributed number of triangles added? This asks whether the entire effect of geometry at this scale is a few extra triangles.
Experts, Q29 of 70“The idea that high-dimensional geometric dependence reduces to Erdős–Rényi plus a simple Poisson triangle correction is appealing, and a counterexample would expose genuinely hidden structure.”
In the contact process, infected sites recover at rate one and infect each healthy neighbor at rate $\lambda$. On the integer line at the critical rate $\lambda_{\mathbb Z}$, an infection started from finitely many sites always dies out. Now join three half-lines at a single vertex. Each arm alone still dies out at this rate, but the arms can reinfect one another through the junction. Starting with only the junction infected, does the infection survive forever with positive probability at $\lambda_{\mathbb Z}$? This asks whether reinfection through one junction is enough to turn critical extinction into survival.
Expert, Q01 of 70“I like this question a lot. The model is natural, the question is focused, and either a positive or a negative answer would deepen our understanding of the critical contact process.”
On an infinite square grid, an inactive site becomes active only when at least two neighbors are active. Active sites deactivate at rates chosen randomly and then held fixed. Starting with all sites active, does arbitrarily weak spatial variation make the average fraction of active sites at long times rise continuously from zero as the activation rate increases through the onset of sustained activity? This tests whether randomness can smooth an abrupt transition in a system where complete inactivity is permanent.
Expert, Q14 of 70“This question is natural and important. Even if there is already a physical prediction, a rigorous proof in this dynamical model would still be very valuable.”
Agent42 raises the share of interesting questions. We ran an expert study on phase transitions in random structures, a subfield of mathematics, with questions generated by GPT 5.6 Sol. The share of questions that experts judged interesting rises from 3% for initial Agent42 proposals to 33% for final questions after the development loop (Figure 1(d)).
3.2 Solution attempts sharpen or redirect research questions
Solution attempts supplied concrete reasons to change a research target. An expert in phase transitions in random structures selected four trajectories among the final questions and commented on how each question changed over two rounds of development. In the first, solving opens a new direction that the next round turns into a structural conjecture. In the second, solving finds a comparison that shows the phenomenon more clearly. In the third, solving shows that a first revision still falls short of the goal. In the fourth, solving corrects the intuition behind the original question.
A Poisson subset-sum law for near-optimal lattice paths
Give each vertex of the square lattice an independent exponential reward of mean one. For paths $\pi$ from $(0,0)$ to $(n,n)$ using right and up steps, let $H(\pi)$ be the total reward and $L_n=\max_\pi H(\pi)$, with $L_n/n\to4$.
- Initial question
For $\beta>0$, with $Z_n(\beta)=\sum_\pi e^{\beta H(\pi)}$ and $f(\beta)=\lim_{n\to\infty}n^{-1}\mathbb E\log Z_n(\beta)$, does $\beta[f(\beta)-4\beta]$ approach a finite, positive constant as $\beta\to\infty$?
- Round 1
What solving found. Two attempts wrote out arguments that the constant is $\pi^2/24$. Their calculations traced the correction to local detours near the best path, each flipping a corner of the path at a small cost.
How the question changed. The average alone does not show how these detours combine. The revision let the inverse temperature grow with the path length and asked whether $\log Z_n(n)-nL_n$ converges in distribution to $\sum_{x\in\Pi}\log(1+e^{-x})$, where $\Pi$ is a rate-$1/2$ Poisson process on $(0,\infty)$. Each point of $\Pi$ stands for the scaled cost of one detour, which is either taken or not.
Expert comment“Solving drew attention to the low-cost local detours near the optimal path, and suggested a way to study the random contribution these detours make together. In this step, solving found a more concrete and more explanatory research direction.”
- Round 2
What solving found. Solving proved that $\log Z_n(n)-nL_n$ is asymptotically a sum of terms $\log(1+e^{-n\delta})$, one for each local gap $\delta$, and bounded how often small gaps occur together. Computations on the best four paths showed that two detours that do not interfere can be taken separately or together, and their deficits add. The Poisson limit itself remained unproved.
How the question changed. The revision asked about all near-optimal paths at once. Is every scaled deficit a sum of basic detour costs, with the costs forming a Poisson process? This is the final question.
Expert comment“Compared with studying only the sum of all paths’ contributions, this question describes the relations between different paths more directly. The key idea had already formed in the first round. The value of the second round was to organize these ideas, through path decomposition and numerical computation, into a clearer structure and conjecture.”
- Final question
Does the counting measure of scaled deficits $n[L_n-H(\pi)]$, counting each path once, converge in distribution, vaguely on $[0,\infty)$ as $n\to\infty$, to the counting measure of all finite subset sums of a rate-$1/2$ Poisson process on $(0,\infty)$, including zero?
Macroscopic distance uncertainty in almost identical spanning trees
Give the edges of the complete graph on $n$ vertices independent exponential costs $W_e$ of mean one. Given the costs, sample a spanning tree $T$ with probability proportional to $\exp(-bn^{4/3}\sum_{e\in T}W_e)$, for a fixed $b>0$. Large $b$ favors the minimum spanning tree. Write $d_T$ for the graph distance in $T$.
- Initial question
Does the rescaled tree $(T,n^{-1/3}d_T,n^{-1}\sum_v\delta_v)$ converge in distribution in the Gromov–Hausdorff–Prokhorov topology? Do the limits vary with $b$ and approach the minimum-spanning-tree scaling limit as $b\to\infty$?
- Round 1
What solving found. Solving proved local results but not the full limit. A calculation on a single cycle exposed a blind spot. A spanning tree of a cycle deletes one edge. Averaged over the costs, the deleted edge is uniform at every temperature, so the law of one tree does not change with temperature. Two trees sampled with the same costs can still delete different edges, and distances in them then differ on the macroscopic scale.
How the question changed. The revision fixed the costs and two endpoints, sampled two trees, and asked whether their rescaled distance difference $\Delta_n(b)$ stays positive at every temperature and vanishes as $b\to\infty$. This is the final question.
Expert comment“The original question hoped to find a geometric limit that varies with temperature, but a computation on a simple cycle revealed a blind spot. This change makes the question more focused, and it provides a comparison that shows the phenomenon of interest more clearly.”
- Round 2
What solving found. Solving added proof ideas for the new question, including a lower bound from resampling parts of a tree, a reduction to rooted forests, and the exact limit for an isolated cycle. Positivity at every temperature remained unproved.
How the question changed. Development proposed asking for the exact rate at which the difference vanishes, namely whether $b_n\Delta_n(b_n)$ tends to one constant for every sequence $b_n\to\infty$. Three model judges each compared it with the current question, and two of the three preferred the new version. A revision is adopted only when all judges prefer it, so the second-round update was not adopted.
Expert comment“The second round helped explore how to solve it, but brought no new change to the final question. The main improvement to the question itself happened in the first round.”
- Final question
Sample two trees $T^{(1)},T^{(2)}$ independently given the same costs, and choose vertices $U,V$ uniformly at random. Let $\Delta_n(b)=\mathbb E\bigl[\min\{1,n^{-1/3}|d_{T^{(1)}}(U,V)-d_{T^{(2)}}(U,V)|\}\bigr]$. Does $\Delta_n(b)$ converge to a limit $\Delta(b)$ that is positive for every $b$ and tends to $0$ as $b\to\infty$?
A zero-temperature interface in a fixed random environment
At low temperature, the boundary between the plus and minus phases of a planar Ising model is a random interface. A weak random field rewards the signed area that the interface sweeps out. In the continuum, write $B$ for a Brownian bridge on $[0,1]$, $W$ for Gaussian white noise on $[0,1]\times\mathbb R$, and $W(g_x)$ for the noise integrated against $g_x(t,y)=\mathbf 1_{\{0<y<x(t)\}}-\mathbf 1_{\{x(t)<y<0\}}$, the signed region between a path $x$ and the axis.
- Initial question
In the box $\{0,\ldots,L\}\times\{-L,\ldots,L\}$ at large fixed inverse temperature, impose plus boundary spins above height zero and minus below, and add independent Gaussian fields of strength $\lambda L^{-3/4}$. Given the field, does the law of the rescaled interface height $L^{-1/2}H_L$ converge to the law of $B$ tilted by a density proportional to $\exp\{c\,W(g_B)\}$, for an explicit constant $c$?
- Round 1
What solving found. Both attempts wrote out arguments that the proposed continuum limit holds. Computing the thermal fluctuations of the interface in this continuum model then showed that, as the influence of the random field grows, the interface should concentrate on a single random curve.
How the question changed. The revision moved to the continuum model itself. Weight $B$ by a density proportional to $\exp\{c\,W(g_B)\}$ and let $c\to\infty$. After heights are rescaled by $c^{-2/3}$, does this measure converge to a point mass at a random curve $X_*$ that is not deterministic?
Expert comment“The first round computed the interface’s thermal fluctuations and found a phenomenon worth pursuing. The value of this round is that solving moved the research from building a model to the geometric phenomenon the model itself exhibits.”
- Round 2
What solving found. Solving proved that along subsequences the limit is a point mass at a random curve, and that two interfaces sampled at the same low temperature come together. It could not show that every subsequence gives the same curve. As the temperature decreases further, the shared curve might still change, and convergence of the laws of the shape would not detect this.
How the question changed. The revision rewrote the model at temperature $\varepsilon$ with one fixed noise $W$, and asked whether cooling selects a single curve determined by the noise. This is the final question.
Expert comment“To answer the shape question raised in the first round, one also needs to know whether this dependence on temperature eventually stabilizes. I find this step very valuable. Solving made clear which step was still missing between the existing results and the goal, and turned that step into a more concrete question.”
- Final question
At temperature $\varepsilon>0$, let $\mu_{\varepsilon,W}$ be the law of $\sqrt\varepsilon B$ reweighted by $\exp\{\varepsilon^{-1}W(g_x)\}$, with the same noise $W$ at every temperature. Is there a curve $X_*(W)$, determined by the noise, such that $\mu_{\varepsilon,W}$ converges in probability to the point mass at $X_*(W)$ as $\varepsilon\downarrow0$?
A Poisson triangle representation of sparse geometry
This is the question of Example 1, now followed through its development. Sample $n$ independent uniform points on the unit sphere in $\mathbb R^d$. Join pairs whose inner product exceeds a threshold giving edge probability $p_n=(1+\lambda n^{-1/3})/n$, for fixed $\lambda\in\mathbb R$. Compare this geometric graph with an Erdős–Rényi graph having independent edges of probability $p_n$.
- Initial question
Find the dimension scale where geometry becomes hard to detect and characterize the log of the geometric-to-Erdős–Rényi probability ratio. Can this log-ratio be recovered from breadth-first queue-length histories and non-tree edge locations of components with order $n^{2/3}$ vertices?
- Round 1
What solving found. At $d\sim c(\log n)^3$, the attempts derived a Poisson number of triangles with mean $e^{\sqrt{8/c}}/6$, against $1/6$ under independent edges. They showed that triangles usually lie outside the large components that the initial question focused on, and that the records of those components cannot recover the probability ratio. If any finite family of cycle counts suffices, triangle counts alone suffice.
How the question changed. The revision replaced the separate detection targets with one generative model. Add a Poisson number of uniformly random triangles to the Erdős–Rényi graph. Is the result asymptotically equal to the geometric graph in total variation? This is the final question.
Expert comment“Solving gradually corrected the intuition about where the geometric information is hidden. This rewrite organized the originally scattered questions into an intuitive generative mechanism, and also corrected the initial direction of the search for geometric information.”
- Round 2
What solving found. Solving asked what difference remains once the triangles are added. It showed that, up to a growing size, other local structures carry no extra geometric information. Patterns with many more edges than vertices remained out of reach.
How the question changed. The question was kept. Total variation requires all graph-event probabilities to agree asymptotically, so the question asks whether triangles explain every difference between the two graphs.
Expert comment“The key question that ultimately needs to be solved remains whether triangles are enough to explain all the differences in the whole graph. The second round further clarified the hardest step this conjecture has to cross.”
- Final question
When $d/(\log n)^3\to c>0$, is the geometric graph asymptotically equal in total variation to Erdős–Rényi plus $M$ added triangles, where $M\sim\operatorname{Pois}((e^{\sqrt{8/c}}-1)/6)$? Independently of the base graph, sample $M$ and choose $M$ independent uniform three-element vertex subsets, allowing the same subset to repeat. Add all three edges within each subset.
3.3 Results remain uneven across fields
The share of final questions that experts judged interesting varies widely across subfields (Figure 2). It ranges from 47% in phase transitions in random structures, a subfield of mathematics, to 0% in plasma physics. More mathematical subfields tend to have higher shares. Online algorithms and black hole ringdown reach 33% and 30%, while prediction-powered inference, a more methodology-driven subfield of statistics, reaches 14%. Subfields of the same field can also differ sharply, as in physics, where experts judged 3 of 10 black hole ringdown questions interesting and none of the 10 plasma physics questions.
3.4 Most questions build directly on known work
In phase transitions in random structures, 97 of 100 initial proposals and 61 of 70 final questions build directly on known work, by combining known ideas, relaxing an assumption, or taking the next step on a known object (Figure 3). We call these three moves composition. Composition can produce strong questions, and several that experts singled out are careful next steps on known objects. The questions that founded this subfield arose differently. Broadbent and Hammersley (1957) introduced percolation to model a fluid spreading through a random medium, and Erdős and Rényi (1960) asked how the structure of a random graph changes as its edges are added one by one. Each created a new object and a new line of questions instead of modifying an existing one. Questions of this kind are rare among the proposals, which marks a limitation of current AI question generation.
4 Failure Analysis: When Proposed Questions Fail
Weak questions exhibit recurring problems in research motivation and formulation. Expert comments on weak questions point to three recurring problems. In an unnatural combination, the components do not interact in a meaningful way, so together they do not form a compelling research target. In engineered complexity, added assumptions, parameters, or constructions make the problem harder without isolating a meaningful phenomenon. A question can also have an unclear contribution beyond prior work, leaving open what it adds to existing results or previously posed questions. The examples below give a condensed version of one question for each problem.
Can fragmented networks remember their initial opinions?
Start from a uniformly random $4$-regular graph on $n$ vertices with independent uniform opinions $\sigma_i(0)\in\{-1,1\}$. At each step, pick a uniformly random edge whose endpoints disagree. One endpoint, chosen at random, adopts the other’s opinion with probability $1-r$, and with probability $r$ replaces the edge by one to a random non-neighbor that shares its opinion. The process stops when no such edge remains, leaving a final graph $G_\infty$. Let $\mathcal R_n(r)=\sup_{\widehat{\sigma}}\mathbb E\bigl|\frac{1}{n}\sum_i\widehat{\sigma}_i(G_\infty)\sigma_i(0)\bigr|$ be the best overlap with the initial opinions achievable from $G_\infty$ alone, and let $L_2(G_\infty)$ be the size of its second-largest component. For every fixed $r\in(0,1)$, is it true that
The weakness. Two expert rankings place it 63rd and 64th among the 70 questions in mathematics.
Expert comment“I do not particularly like this question. It ties two hard problems directly together, the combination feels forced, and it does not explain why the question should be posed this way.”
Aging of return probabilities on a critical tree
Fix $d\ge3$ and $0<\gamma<1$. On the infinite $d$-regular tree, each edge carries an independent renewal clock with waiting times satisfying $\mathbb P(T>s)=(1+s)^{-\gamma}$. At time zero and at each renewal, the edge is declared open independently with the critical percolation probability $p=1/(d-1)$. A walker $X_t$ starts at the root and, at the rings of a rate-one Poisson clock, tries to step to a uniformly chosen neighbor, succeeding only across an open edge. Show that the limit
exists for every $\theta>0$ and determine it.
The weakness. Two expert rankings place it 58th and 45th among the 70 questions in mathematics.
Expert comment“The question is meaningful and could distinguish two aging mechanisms. With three layers of randomness combined, however, the central question no longer stands out.”
Does pinning the core preserve singular response?
Sample $G\sim G(n,c/n)$ with $c$ above the threshold for a rigid component of linear size, place the vertices at independent standard Gaussian points in the plane, and treat each edge as a spring. Let $K_n$ be the stiffness matrix of the largest rigid component, which has $r_n$ vertices. Let $A_n$ be its restriction to the vertices outside the component’s $3$-core, which describes the response when the core is held fixed. Define
Prove or refute that there exist $B(c)$ and $\eta_0(c)>0$ such that, for every fixed $0<\eta<\eta_0(c)$, the inequality $\chi_n(\eta)\le B(c)\,p_n(\eta)$ holds with probability tending to one.
The weakness. Two expert rankings place it 37th and 51st among the 70 questions in mathematics. Both reviews describe it as a lemma within an existing line of research.
Expert comment“I usually like spectral questions, but comparing full and core-pinned responses feels more like a lemma in a rigidity project than a standalone problem.”
Scientific writing problems occur in both strong and weak questions. Incorrect terminology and nonstandard phrasing can obscure the intended meaning. The motivation and essential explanations are often compressed or omitted, while routine details receive excessive attention. Unlike the problems above, these lie only in the exposition.
5 Research Taste: Do Model Judges Agree with Experts?
5.1 Model judges cannot yet fully replace expert research taste
We compare GPT 5.6 Sol, Astra, Fable 5.1, and Opus 5.5 with eight experts who ranked 70 generated questions in probability and statistical physics. Expert rankings are noisy below the top, so we compare shortlists, the questions each judge ranks highest.
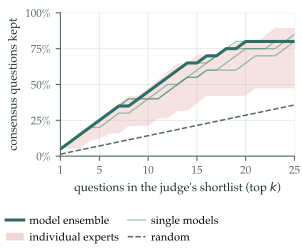
Model shortlists recover what experts agree on. Twenty questions form a consensus set, each placed in the top 20 by several experts. A single model’s top 20 keeps 13 to 16 of them, at the upper end of what one expert’s top 20 keeps of the questions the other experts agree on. The mean ranking of the four models keeps 16 (Figure 4, left).
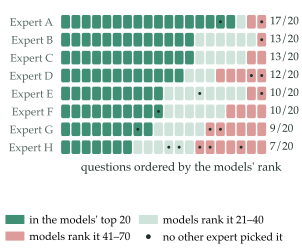
They miss what individual experts value. How closely the models’ top 20 matches an expert’s top 20 varies widely. It contains 17 of one expert’s top 20 but only 7 of another’s (Figure 4, right). Of the 16 questions that only one expert placed in the top 20, the models’ top 20 contains 3, fewer than a random shortlist would. Models can help prioritize questions, but relying on their shortlists would discard the questions that matter most to an individual expert.
The question. In a random spring network, do the two lowest-frequency orthogonal vibration modes concentrate on the same weak regions? The proposed target is a precise limiting distribution for their spatial overlap as the network grows.
The disagreement. One expert ranks this ninth out of 70; the four models place it between 44th and 66th. The expert values what shared weak spots would reveal about the network. Opus questions the payoff of the precision demanded by this distribution.
Expert comment; RMT means random matrix theory“I like the RMT-style question of whether two low-lying eigenvectors share rare weak spots, and I do not see why they necessarily should.”
5.2 What experts look for in a question
From the experts’ feedback on individual questions, we distill five criteria they apply repeatedly.
- Naturalness. It is a natural problem for the field rather than an ad hoc construction, with one clear focus instead of many new definitions or several separate targets.
- Explanatory value. It addresses a phenomenon that is not yet understood, ideally one where either outcome would be informative.
- Motivated combinations. Combining familiar ideas requires a reason to expect something new from their interaction. Experts reject “A+B” questions that join known ingredients without a common mechanism.
- Conceptual difficulty. Extending a known result is worthwhile when it requires new ideas, not when existing methods suffice. A precise quantitative target should be motivated by the mechanism behind it.
- A tractable starting point. The question admits a concrete first step that is worth doing on its own.
One expert summarized these criteria as a test. A good question survives simplification and an honest first attempt to solve it. The development loop of Agent42 is designed around the second part of this test.
The examples below are questions that most experts ranked highly.
Do optimal matchings differ on a large scale?
In a sparse random network, pair up as many linked vertices as possible. There are usually many optimal pairings. Take two of them at random and look at where they differ. Do the differences form chains that span a positive fraction of the network, and if so, from which density of links onward?
What experts value. Six of the eight experts rank this among their top five. The model is natural, and the question asks for a sharp structural change whose answer either way would reveal something about the space of optimal solutions.
Expert comment“I appreciate that this is easy to state and asks for a sharp structural change among optimal matchings, with either macroscopic exchanges or genuine rigidity teaching us something.”
Can removing an inactive constraint move the optimum far away?
Draw random constraints, three times as many as the dimension, and find the point on a high-dimensional sphere that satisfies all of them with the largest margin. Some constraints are not tight at this optimum, so removing one of them changes nothing nearby. Can it still move the optimum to a distant point?
What experts value. Six of the eight experts rank this among their top 15. One finds it counterintuitive that a constraint with no local effect could still change the global optimum, which would separate local stability from the selection of the global optimum.
How are near-optimal paths built?
Put a random reward on each site of a grid and consider all up-right paths between two corners. The proposal is that the next-best paths are the best path modified by a few small, separate detours, so that their shortfalls add up from independent pieces. Is the rescaled list of shortfalls described by the sums of all finite subsets of a random scatter of points?
What experts value. Seven of the eight experts rank this among their top 15. One expert notes that the full distribution may be hard to establish, but the question offers a concrete route, and understanding its core structure would already be valuable.
Expert comment“Although specialized, the Poisson subset-sum picture gives an intuitive way to understand how near-optimal paths are built from elementary local changes.”
5.3 Where models and experts disagree
Our model judges were given principles close to these. They were told to prefer natural questions with one central tension, to let every extra definition or parameter earn its place, and not to reward a routine A+B combination. Their explanations use the same language, and at the extremes they agree with the experts. All eight experts and all four models rank the matching question above in their top 25. All of them place in their bottom third a question that assumes a harder open problem is solved and asks only for a constant that follows from it.
Between these extremes, models and experts often read the same question differently. The models grade the precise conjecture a question states, while experts more often ask what settling it would teach us, whichever way it resolves. The models also accept an elaborate formulation when they see one idea behind it, where experts more often see several hard problems stacked together. The examples below show one case of each.
Is a handful of extra triangles all that geometry leaves behind?
Place points at random on a high-dimensional sphere and connect each pair that is close. At the dimension where geometry becomes barely detectable, the resulting sparse network looks almost like one with purely random connections, except that it contains a few more triangles. Is that the whole difference? Is the geometric network indistinguishable from a purely random network with a random number of extra triangles added?
The disagreement. Seven of the eight experts place this question in their top 15, and it is among the five favourites of the additional expert. The four-model ensemble ranks it 36th. Fable and Opus read it as a sharp refinement of a known threshold for detecting geometry, with a predictable mechanism and a parameter that plays no role. The experts instead value the question itself.
Expert comment; Erdős–Rényi means a network with purely random connections“The idea that high-dimensional geometric dependence reduces to Erdős–Rényi plus a simple Poisson triangle correction is appealing, and a counterexample would expose genuinely hidden structure.”
When does the curvature of space change connectivity?
Color each cell on a negatively curved surface black with the same probability, independently. As the surface becomes flatter, what is the limiting geometry of black clusters when their characteristic size is comparable to the curvature radius? How does the probability threshold for an infinite black cluster shift?
The disagreement. All four models rank this among their top eight of 32, valuing the competition between cluster size and curvature radius as the source of a new limiting object. One expert sees several known open problems stacked together, and another finds the formulation too complicated to count as a natural problem. A third finds the core very appealing but would start from a simpler model.
The question about vibration modes in Section 5.1 follows the first pattern. Fable and Opus call its conjectured law and constant “reverse-engineered” or “a constant-level verification,” while the experts who rank it highly care whether two different modes concentrate on the same weak spots.
Experts ask for a way in; the models were told not to. The judges’ instructions say that difficulty is not a negative signal, and that a natural question should not be ranked lower because no route to a solution is visible. Experts weigh exactly this, as the suggestion to start from a simpler model shows. This difference lies in the instructions, not in the models.
Some disagreements are not about taste. A reviewer who believes a result is already known, doubts what an observable can detect, or misreads the question is judging something else. We set such cases aside before reading a disagreement as a difference in taste. The examples below show one case of each.
Does a random walker notice when infinite clusters merge?
As random connections are added to a hyperbolic lattice, many infinite clusters give way to a single one. Is the long-run rate of growth of uncertainty about a walker’s position continuous through this transition?
The disagreement. Fable and Opus rank this second of 32, praising its single informative observable. Two experts point to existing continuity results that may already cover it. Until the assumptions and timing of those results are checked, this is a possible gap in literature knowledge, not a difference in taste.
Does agreement between low-cost assignments signal a transition?
Match $n$ workers to $n$ jobs with independent exponential costs of mean one. Using the same costs, sample two assignments independently, giving each assignment of total cost $C$ weight $\exp(-tnC)$ for $t>0$. As $n$ grows, does their fraction of shared pairs approach a positive value for every $t>0$, or only above a threshold?
The disagreement. GPT 5.6 Sol sees a clean test of concentration onto common assignments. Astra argues that a few locally competitive choices may already produce overlap, so positive overlap need not reveal a distinct global transition. This objection requires checking; it does not show a dislike of studying the structure of low-cost assignments.
Can an avalanche suppress another without changing its trigger region?
In a sandpile, adding a grain can trigger a cascade of topplings. Can an earlier avalanche prevent a later one from reaching the boundary even when, after the first avalanche ends, every particle count near the second trigger has returned to its original value?
The disagreement. Some Opus explanations describe the avalanches as “independent” or “non-interfering,” missing the requested suppression by changes farther away. Another explanation reads the event correctly. The mistaken readings are excluded from evidence about taste.
5.4 Conditioning the judge on individual experts
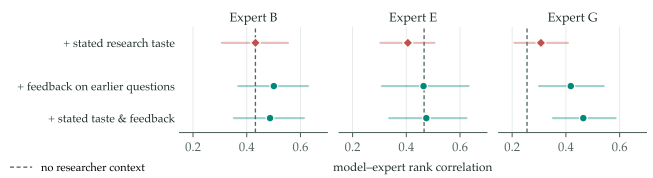
Can a model judge learn to rank like a particular expert? We condition Astra on each of three experts using two sources of evidence, alone and combined: the expert’s stated research taste, a self-reported statement of the qualities they value together with papers they like or dislike and why, and their feedback on 33 earlier questions generated by Agent42.
Stated research taste does not improve alignment. Conditioning on stated taste does not bring the judge closer to the expert (Figure 5). The stated rationales largely coincide with the guideline we already provide to the judge. What the judge lacks is how an expert applies these principles, for example which questions they consider natural and which outcomes they would find surprising.
Feedback on earlier questions improves alignment. Feedback shows how an expert applies these principles to concrete questions. It raises the correlation with one expert from 0.26 to 0.42, with incremental gains for the other two. Adding stated taste to feedback yields no further clear gain. Examples of an expert’s judgments thus convey individual taste more effectively than a self-report.
6 Limitations and Future Steps
- Dependence on expert evaluation. We do not yet have a reliable automatic evaluator of research interestingness. Final assessments rely on experts, whose limited availability constrains evaluation scale.
- Limited evaluation scale. Our evaluation covers a limited set of questions, subfields, and experts. In particular, our profile-conditioning experiments use profiles from only three experts.
- Theoretical fields. Our study currently focuses on theoretical fields. We hope to extend this work to a broader range of scientific fields.
- Cultural and experimental aspects of interestingness. What makes a research question interesting can be shaped by both research culture and empirical evidence. A field’s literature and research traditions influence which questions researchers value, while new data and observations can motivate new questions. Agent42 currently focuses more on capturing the cultural aspect and does not gather evidence from the real world. Gathering new evidence and using it to guide question development are important future steps.
- Expert interest as a proxy. Experts’ judgments of interestingness are a proxy for the research value that solving a question could yield. Whether resolving the proposed questions produces valuable insights remains to be established.
7 Discussion
Research activities are intertwined. Solving an open question often requires posing new questions, developing theories, and creating new tools. These developments can reshape the original question and suggest new directions. We view question posing as part of this broader process of building understanding.
The role of researchers. Researchers help determine which questions are worth pursuing. Their differing judgments provide perspectives that can guide how AI systems propose, develop, and evaluate research questions.
An invitation to researchers. Alongside this blog, we release expert-verified research questions on our website for researchers to pursue, revise, or challenge. We invite researchers to help extend After42 to more fields by setting research goals and sharing their expertise. We also welcome comments and suggestions for improving the published questions, so that we can develop better questions together.
Acknowledgements
The authors thank Yuanxi Liu, Xiaodong Tao, Haimeng Zhao, Lei Wu, Yufei Zhao, Hong Wang, Nicolas Flammarion, Jason D. Lee, and Dylan Foster for their insightful advice and feedback.
References
- Artur Avila, Manjul Bhargava, Caucher Birkar, Pierre Deligne, Yu Deng, Simon Donaldson, et al. (2026). A Severe Misalignment of AI in Mathematics.
- Michael P. Brenner, Vincent Cohen-Addad, David Woodruff (2026). Solving an Open Problem in Theoretical Physics using AI-Assisted Discovery. arXiv:2603.04735.
- S. R. Broadbent, J. M. Hammersley (1957). Percolation processes: I. Crystals and mazes. Mathematical Proceedings of the Cambridge Philosophical Society.
- Ivan Corwin (2026). A value-based approach to mathematics.
- Silvia De Toffoli, Eamon Duede (2026). After Math.
- Paul Erdős, Alfréd Rényi (1960). On the evolution of random graphs. Publications of the Mathematical Institute of the Hungarian Academy of Sciences.
- Imre Lakatos (1976). Proofs and Refutations: The Logic of Mathematical Discovery. Cambridge University Press.
- Terence Tao (2026). Mathematics in the age of AI. arXiv:2608.16753.
- William P. Thurston (1994). On proof and progress in mathematics. Bulletin of the American Mathematical Society.